

Get started with AI Observability
This guide demonstrates how to implement real-time cost tracking, token usage monitoring, hallucination detection, and latency optimization for your AI applications with OpenTelemetry traces and metrics.
flowchart TB; subgraph " " direction LR; subgraph " " direction LR; Shield360_SDK[Shield360 SDK] -->|Sends Traces & Metrics| OTC[OpenTelemetry Collector]; OTC -->|Stores Data| ClickHouseDB[ClickHouse]; end subgraph " " direction RL; Shield360_UI[Shield360] -->|Pulls Data| ClickHouseDB; end endSign in at app.shield360.ai, or self-host Shield360. The examples below send to a self-hosted Shield360 on this machine; for app.shield360.ai, use its address and an API key from Settings → API keys.
pip install shield360npm install shield360import shield360
shield360.init(otlp_endpoint="http://127.0.0.1:4318")Examples:
from openai import OpenAIimport shield360
shield360.init(otlp_endpoint="http://127.0.0.1:4318")
client = OpenAI(    api_key="YOUR_OPENAI_KEY")
chat_completion = client.chat.completions.create(    messages=[        {            "role": "user",            "content": "What is LLM Observability?",        }    ],    model="gpt-3.5-turbo",)
import osfrom anthropic import Anthropicimport shield360
shield360.init(otlp_endpoint="http://127.0.0.1:4318")
client = Anthropic( # This is the default and can be omitted api_key=os.environ.get("ANTHROPIC_API_KEY"),)
message = client.messages.create( max_tokens=1024, messages=[ { "role": "user", "content": "Hello, What is LLM Observability?", } ], model="claude-3-opus-20240229",)import cohereimport shield360
shield360.init(otlp_endpoint="http://127.0.0.1:4318")
co = cohere.Client( api_key="YOUR_API_KEY",)
chat = co.chat( message="hello world!", model="command")from litellm import completionimport osimport shield360
shield360.init(otlp_endpoint="http://127.0.0.1:4318")
os.environ["HUGGINGFACE_API_KEY"] = "huggingface_api_key"
# e.g. Call 'WizardLM/WizardCoder-Python-34B-V1.0' hosted on HF Inference endpointsresponse = completion( model="huggingface/WizardLM/WizardCoder-Python-34B-V1.0", messages=[{ "content": "Hello, how are you?","role": "user"}], api_base="https://my-endpoint.huggingface.cloud")from langchain_core.messages import HumanMessage, SystemMessageimport shield360
shield360.init(otlp_endpoint="http://127.0.0.1:4318")
from langchain_openai import ChatOpenAI
model = ChatOpenAI(model="gpt-4o-mini")
messages = [ SystemMessage(content="Translate the following from English into Italian"), HumanMessage(content="hi!"),]
model.invoke(messages)import ollamaimport shield360
shield360.init(otlp_endpoint="http://127.0.0.1:4318")
response = ollama.chat(model='llama3.1', messages=[ { 'role': 'user', 'content': 'Why is the sky blue?', },])Add the following two lines to your application code:
import shield360
shield360.init()
Run the following command to configure the OTEL export endpoint:
export OTEL_EXPORTER_OTLP_ENDPOINT = "http://127.0.0.1:4318"Examples:
from openai import OpenAIimport shield360
shield360.init()
client = OpenAI(    api_key="YOUR_OPENAI_KEY")
chat_completion = client.chat.completions.create(    messages=[        {            "role": "user",            "content": "What is LLM Observability?",        }    ],    model="gpt-3.5-turbo",)
import osfrom anthropic import Anthropicimport shield360
shield360.init()
client = Anthropic( # This is the default and can be omitted api_key=os.environ.get("ANTHROPIC_API_KEY"),)
message = client.messages.create( max_tokens=1024, messages=[ { "role": "user", "content": "Hello, What is LLM Observability?", } ], model="claude-3-opus-20240229",)import cohereimport shield360
shield360.init()
co = cohere.Client( api_key="YOUR_API_KEY",)
chat = co.chat( message="hello world!", model="command")from litellm import completionimport osimport shield360
shield360.init()
os.environ["HUGGINGFACE_API_KEY"] = "huggingface_api_key"
# e.g. Call 'WizardLM/WizardCoder-Python-34B-V1.0' hosted on HF Inference endpointsresponse = completion( model="huggingface/WizardLM/WizardCoder-Python-34B-V1.0", messages=[{ "content": "Hello, how are you?","role": "user"}], api_base="https://my-endpoint.huggingface.cloud")from langchain_core.messages import HumanMessage, SystemMessageimport shield360
shield360.init()
from langchain_openai import ChatOpenAI
model = ChatOpenAI(model="gpt-4o-mini")
messages = [ SystemMessage(content="Translate the following from English into Italian"), HumanMessage(content="hi!"),]
model.invoke(messages)import ollamaimport shield360
shield360.init()
response = ollama.chat(model='llama3.1', messages=[ { 'role': 'user', 'content': 'Why is the sky blue?', },])# Install Shield360pip install shield360
# Configure via CLI argumentsshield360-instrument \ --service-name my-ai-app \ --environment production \ --otlp-endpoint http://127.0.0.1:4318 \ python your_app.py# Configure via environment variablesexport OTEL_SERVICE_NAME=my-ai-appexport OTEL_DEPLOYMENT_ENVIRONMENT=productionexport OTEL_EXPORTER_OTLP_ENDPOINT=http://127.0.0.1:4318
# Run with zero code changesshield360-instrument python your_app.pyimport Shield360 from "shield360"
Shield360.init({ otlpEndpoint: "http://127.0.0.1:4318" })Examples:
import Shield360 from "shield360"
Shield360.init({ otlpEndpoint: "http://127.0.0.1:4318" })
async function main() { const OpenAI = await import("openai").then((e) => e.default); const openai = new OpenAI({ apiKey: process.env.OPENAI_API_KEY, }); const completion = await openai.chat.completions.create({ model: "gpt-3.5-turbo", messages: [{ role: "user", content: "What is LLM Observability?" }], });
console.log(completion?.choices?.[0]);}
main();import Shield360 from "shield360"
Shield360.init({ otlpEndpoint: "http://127.0.0.1:4318" })
async function main() { const Anthropic = await import("@anthropic-ai/sdk").then((e) => e.default); const anthropic = new Anthropic({ apiKey: process.env.ANTHROPIC_API_KEY, }); const message = await anthropic.messages.create({ max_tokens: 1024, messages: [{ role: "user", content: "Hello, What is LLM Observability?" }], model: "claude-3-opus-20240229", });
console.log(message);}
main();import Shield360 from "shield360"
Shield360.init({ otlpEndpoint: "http://127.0.0.1:4318" })
async function main() { const { CohereClient } = await import("cohere-ai"); const cohere = new CohereClient({ token: process.env.COHERE_API_KEY, }); const chat = await cohere.chat({ message: "hello world!", model: "command", });
console.log(chat);}
main();import Shield360 from "shield360"
Shield360.init({ otlpEndpoint: "http://127.0.0.1:4318" })
async function main() { const { ChatOpenAI } = await import("@langchain/openai"); const { HumanMessage, SystemMessage } = await import("@langchain/core/messages");
const model = new ChatOpenAI({ model: "gpt-4o-mini" });
const messages = [ new SystemMessage("Translate the following from English into Italian"), new HumanMessage("hi!"), ];
await model.invoke(messages);}
main();import Shield360 from "shield360"
Shield360.init({ otlpEndpoint: "http://127.0.0.1:4318" })
async function main() { const ollama = await import("ollama").then((e) => e.default); const response = await ollama.chat({ model: "llama3.1", messages: [{ role: "user", content: "Why is the sky blue?" }], });
console.log(response);}
main();Add the following two lines to your application code:
import shield360 from "shield360"
shield360.init()
Run the following command to configure the OTEL export endpoint:
export OTEL_EXPORTER_OTLP_ENDPOINT = "http://127.0.0.1:4318"Examples:
import shield360 from "shield360"
shield360.init()
async function main() {  const OpenAI = await import("openai").then((e) => e.default);  const openai = new OpenAI({      apiKey: process.env.OPENAI_API_KEY,  });  const completion = await openai.chat.completions.create({      model: "gpt-3.5-turbo",      messages: [{ role: "user", content: "What is LLM Observability?" }],  });
  console.log(completion?.choices?.[0]);}
main();
import shield360 from "shield360"
shield360.init()
async function main() { const Anthropic = await import("@anthropic-ai/sdk").then((e) => e.default); const anthropic = new Anthropic({ apiKey: process.env.ANTHROPIC_API_KEY, }); const message = await anthropic.messages.create({ max_tokens: 1024, messages: [{ role: "user", content: "Hello, What is LLM Observability?" }], model: "claude-3-opus-20240229", });
console.log(message);}
main();import shield360 from "shield360"
shield360.init()
async function main() { const { CohereClient } = await import("cohere-ai"); const cohere = new CohereClient({ token: process.env.COHERE_API_KEY, }); const chat = await cohere.chat({ message: "hello world!", model: "command", });
console.log(chat);}
main();import shield360 from "shield360"
shield360.init()
async function main() { const { ChatOpenAI } = await import("@langchain/openai"); const { HumanMessage, SystemMessage } = await import("@langchain/core/messages");
const model = new ChatOpenAI({ model: "gpt-4o-mini" });
const messages = [ new SystemMessage("Translate the following from English into Italian"), new HumanMessage("hi!"), ];
await model.invoke(messages);}
main();import shield360 from "shield360"
shield360.init()
async function main() { const ollama = await import("ollama").then((e) => e.default); const response = await ollama.chat({ model: "llama3.1", messages: [{ role: "user", content: "Why is the sky blue?" }], });
console.log(response);}
main();Refer to Shield360 SDK configuration reference or TypeScript SDK reference for more advanced configurations and use cases.
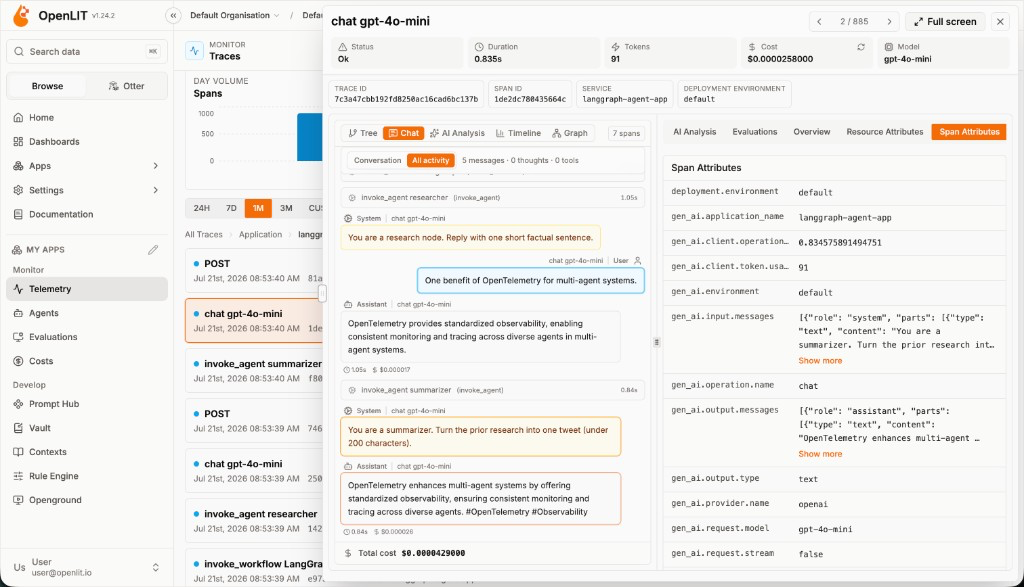
With real-time LLM observability data now flowing to Shield360, visualize comprehensive AI performance metrics including token costs, latency patterns, hallucination rates, and model accuracy to optimize your production AI applications.
Just head over to Shield360 at 127.0.0.1:3000 on your browser to start exploring. Sign in with your administrator account; see First sign-in.
You’re all set! Your AI applications now have observability with real-time performance monitoring, cost tracking, and AI safety evaluations.
Send Observability telemetry to other OpenTelemetry backends
flowchart TB; subgraph " " direction LR; ApplicationCode[Application Code] -->|Instrumented with| Shield360_SDK[Shield360 SDK]; Shield360_SDK -->|Sends Traces & Metrics| OT_Backend[OpenTelemetry Backend]; endIf you wish to send telemetry directly from the SDK to another backend, you can stop the current Docker services by using the command below. For more details on sending the data to your existing OpenTelemetry backends, checkout our Supported Destinations guide.
docker compose downIf you have any questions or need support, reach out to our community.